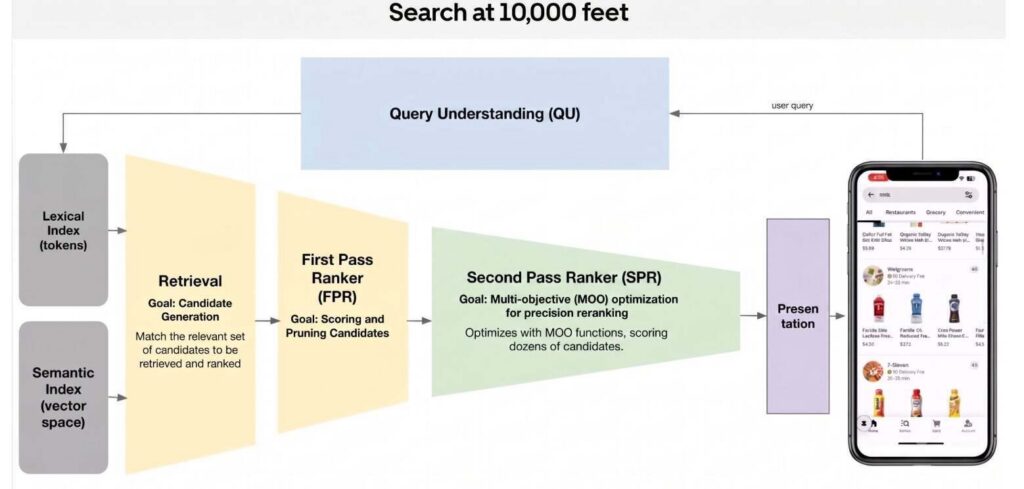
As reported on November 16, 2026, Uber said it had reduced Uber Eats’ end-to-end search latency by 50% through changes across retrieval, feature hydration, ranking, ads, rendering and infrastructure. The result came from multiple optimizations rather than one system-wide redesign.
Uber also changed what it measured. Instead of relying only on backend API response time, it tracked above-the-fold completion: the time from a search request until the first screen of results, including images, had fully rendered. Server-side caching for pagination shortened the initial response, while asynchronous rendering let result items be processed concurrently. Uber reported that these changes cut above-the-fold latency by more than 200 milliseconds.
Before ranking, the pipeline had been populating features for tens of thousands of candidates, many of which would ultimately be discarded. Removing low-value retrieval strategies saved about 120 milliseconds. Product-level embeddings reduced data queries by more than 100-fold and saved another 50 milliseconds. Separating feature hydration for ranking from display data reduced latency by more than 100 milliseconds. Uber attributed further reductions of 35 milliseconds to removing unnecessary dependencies and 40 milliseconds to request hedging.
Changes to the ads path—including column-oriented bidding data, in-memory access and less serialization—reduced latency by about 130 milliseconds. Other infrastructure work included parallel encoding, smaller embedding vectors, connection-management improvements and Go data-structure changes intended to reduce garbage-collection overhead. Uber also introduced agentic-coding workflows to identify, benchmark and validate additional optimizations.
Uber was still exploring end-to-end microbatching, product-based retrieval, Zero Pass Ranking and HTTP multipart streaming. According to the report, early tests of product-based retrieval had reduced p99 latency by more than 50%; that test result is separate from the reported 50% reduction in end-to-end search latency. The planned approaches aim to let pipeline stages overlap rather than wait for earlier stages to finish.